A data scientist explores your data, tests hypotheses, and works out whether a model can answer your question. An ML engineer builds the system that runs that model every day: the training pipeline, deployment, monitoring, and integration with your applications. Companies that hire only data scientists often end up with promising notebooks and nothing in production. Most of our clients need the engineering half, and some need both.
Hire machine learning engineers
Hire pre-vetted ML engineers who can train models, integrate them into .NET applications, and keep them running after launch. They work across the full path from data and model development to deployment, monitoring, and retraining.
Hire machine learning developers
A good model is only half the job. Your ML engineer also needs to know how that model becomes a production service: how to expose it through an API, integrate it with an existing .NET codebase, monitor its performance, and retrain it when production data changes.
Our ML engineers work inside your team, follow your sprints, and report to your technical lead. They bring hands-on experience with Azure ML, MLflow, and production .NET development, so you do not need to split the work between a data science team and a separate implementation team.
Why hiring ML engineers is harder than it looks
-
ML engineers who can’t cross the lab-to-production gap
A model that performs well in a notebook is only the starting point. Someone still has to turn it into a reliable service: package the model, build the deployment pipeline, expose it through an API, monitor its performance, and handle failures. Without that production work, even a strong model stays in a repository instead of becoming part of the product.
-
MLOps treated as an afterthought
A model can perform well at launch and still become less accurate as customer behavior, data, or business conditions change. That is why production ML needs more than a successful initial deployment. Teams need to track model versions, monitor performance, detect data drift, retrain when necessary, and test a new model against the one already in production before switching over. Without these safeguards, a model can get worse until customers notice.
-
ML in isolation, with no path into your enterprise systems
A model must connect to the systems your business already runs. It needs access to the right data, a reliable way to deliver predictions, and integration with the application that uses them. If your ML engineer only builds the model, your .NET team may still have to connect it to the data warehouse, ERP, APIs, and other production systems. That integration can become a project itself, and is often discovered only after the model is finished.
-
The 4 to 9 month hiring process
Hiring an experienced ML engineer can take months, especially when you need someone who combines machine learning with production engineering skills. During that time, the project moves slowly and your existing team has to cover the gap. Nearshore hiring gives you access to experienced engineers sooner, while typically reducing the cost of building the team by 40% to 60%.
What our ML engineers build

Hire machine learning expert
We provide ML engineers who can take a system from data pipelines and model development through MLOps and .NET deployment. You can hire one specialist for a specific feature, or bring in a full team when you need to build the model, data infrastructure, and application integration together.
Our engineers work inside your existing team, follow your development process, and use the same tools and workflows as your in-house developers.
Predictive analytics and ML models
We build supervised and unsupervised learning models, time-series forecasts, and anomaly detection systems using your business data. We start with the decision the model needs to support, then choose an approach that fits the available data, required accuracy, and how the results will be used in production.
MLOps and production deployment
We build the infrastructure needed to run ML models reliably after launch, including CI/CD pipelines, MLflow model versioning, Azure Monitor observability, and automated retraining when performance changes. We introduce these practices during development, so the production environment doesn’t have to be rebuilt around the finished model.
ML integration with .NET
We connect ML models to ASP.NET Core applications, Azure ML endpoints, and REST APIs that your existing services can call. Because our engineers work across both machine learning and .NET, they can handle the integration rather than leaving your application team to turn a finished model into a production feature.
Computer vision and NLP models
We develop models for image classification, object detection, text classification, and document processing, matching engineers to your use-case requirements. For projects involving language models, industrial vision, or more specialized AI applications, we can assemble the appropriate combination of ML and software engineering expertise.
Why hire ML engineers from Blackthorn Vision
-
.NET and ML in one engineer, or one team
ML engineers who understand enterprise .NET architecture are rare on the open market. We have both skill sets on staff, plus bridge engineers who connect them, so there’s no handoff between the person who trains the model and the person who integrates it.
-
Vetted on a production track record
Every engineer goes through a live architecture review, an ML system design exercise, an MLOps scenario, and a code quality check before we put them in front of you. We’re screening for people who have shipped and maintained models, and the interviews are built to find that out.
-
Microsoft Partner with native Azure ML depth
Blackthorn Vision is a Microsoft-partnered .NET and AI development company that helps enterprise teams build and modernize complex software products. In practice, that means deep Azure ML work, Azure OpenAI integration where needed, and Azure Monitor wired into model performance tracking.
-
MLOps from day one
Azure ML, MLflow, GitHub Actions, and model drift detection go in with the first sprint. Your model arrives with the infrastructure to keep it accurate, and you can see how it’s performing without asking anyone.
ML engineering in practice at Blackthorn Vision
Client / Industry: unSkript, an AI-based incident response platform for SRE and DevOps teams. Information technology, USA. Client since 2018.
ML challenge: SRE teams were spending their days on repetitive triage. The platform needed to spot abnormal system behavior, recommend the right remediation, and run it without a human deciding on every step. That meant models working against live production telemetry, where a wrong call has consequences.
ML stack: Our dedicated team built automated health checks for applications and API services, an AI assistant that recommends and creates runbooks, and the .NET and cloud services underneath them. Anomaly detection and recommendation logic run inside the product, in the same codebase the team ships every sprint.
Result: Processes run much faster with far less manual intervention, and the team has a wider set of troubleshooting and remediation options than before. The engagement has run since 2018, through several product generations, with the same core team.
ML technology stack our engineers work with
All technologiesWe pick the stack around your data and latency requirements, and where the model has to run.
ONNX Runtime gets its own place in the list because it lets a model trained in Python run inside a .NET or edge application at speed, which is what industrial and on-premise deployments usually need.
Meet our ML engineering team
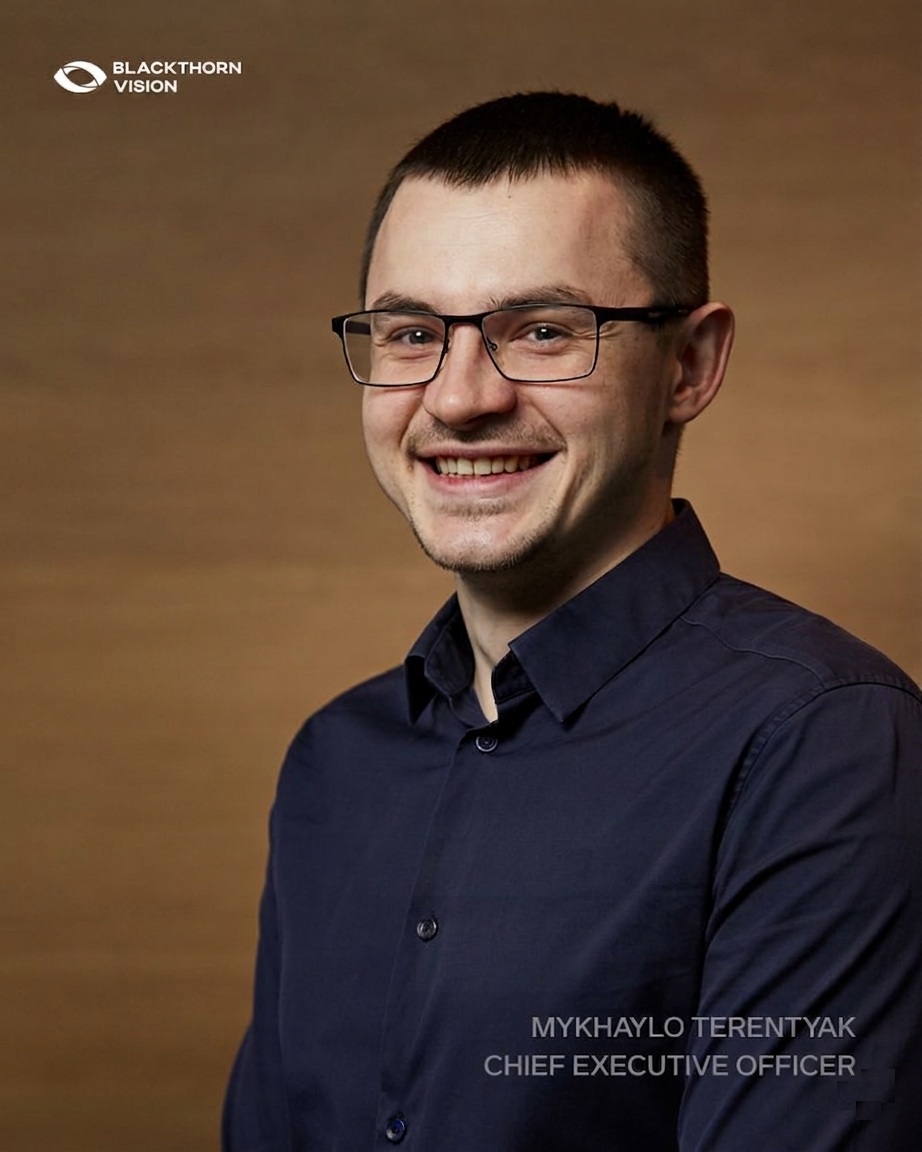
“In an interview, we ask engineers to walk us through a model they have run in production: how it was deployed, what they monitored, what changed after launch, and what they did when performance started to drop. We hire engineers who have dealt with the difficult part of ML — the alerts, retraining, failed deployments, and model versions that had to be rolled back.”
Mykhailo Terentiak, Founder & CEO
How we hire and onboard your ML engineers

-
01
Technical scoping
We start by looking at the ML use case, your current tech stack, the level of experience you need, timezone overlap, and how long you expect the engagement to last. From there, we define the roles, responsibilities, rates, and a realistic start date.
-
02
Vetting and matching
Before you meet a candidate, they go through a live architecture review, an ML system design exercise, and an MLOps scenario. We then share two or three suitable profiles with the assessment results, so you can see what each candidate was tested on and how they performed.
-
03
Your interview
You interview the shortlisted engineers and decide who joins your team. We handle the coordination, answer any technical questions about the assessments, and go back to the search if none of the candidates is the right fit. Once you choose, we agree on the start date.
-
04
Onboarding and integration
We handle the initial setup, including repo access, tools, accounts, and introductions to your development process. The goal is for your engineer to join your standups, work in your existing workflow, and start contributing code from the second week.
FAQ
-
What is the difference between an ML engineer and a data scientist?
-
How quickly can we get an ML engineer started?
Two weeks is the usual timeline from signed scope to first standup. Scoping and vetting take three to five days, interviews take a few more days, and onboarding runs in parallel with contract paperwork. If we already have a matching profile on the bench, it can be faster.
-
Can you hire ML engineers who work with our .NET systems?
Yes, and this is our strongest area. We’ve written .NET since 2009, so our engineers connect models to ASP.NET Core services, Azure Functions, and REST endpoints inside existing enterprise applications. When a model needs to run inside the .NET process, we use ML.NET or ONNX Runtime instead of standing up a separate Python service.
-
What seniority levels are available?
We staff senior ML engineers with five or more years of production experience, mid-level engineers for well-scoped model work under senior direction, and specialist roles like MLOps and data engineering. For most first engagements, we recommend at least one senior on the team, then mid-level capacity around them as the work grows.
-
How do you handle MLOps and model monitoring after deployment?
We build monitoring into the same sprint as the model. We set up model versioning in MLflow, performance tracking through Azure Monitor, and alerts on the metrics that indicate drift for your particular use case. Retraining runs on a schedule or on a trigger, depending on how fast your data changes, and the pipeline is documented so your own team can run it.
-
Do your ML engineers have production deployment experience?
Yes, we screen for it specifically. Our MLOps scenario in the interview asks candidates to walk through a real deployment, including how they version models, how they detect drift, and what they do when accuracy drops on a Friday night. Engineers who have only trained models for research don’t pass that stage.