LLM development is building the application around the model itself, things like prompt design, fine-tuning, and the interface people or systems use to talk to it. RAG development is the retrieval layer that feeds the model facts from your documents before it answers.
LLM & RAG development company
We build custom LLM applications and RAG pipelines that ground AI answers in your enterprise data. Your documents and contracts stay inside your systems, and you don’t get wrong or generic answers.
LLM & RAG development services
A large language model answers from what it learned during training. Ask it about your pricing, your contract terms, or last quarter’s numbers, and it will guess, because it never touched your data. Retrieval-Augmented Generation, or RAG, fixes that: it looks up the real answer in your documents, then has the model write the response from what it found.
We build both halves of that system: the LLM application itself and the RAG pipeline underneath it. Our LLM development services and RAG development services run on Azure OpenAI and Semantic Kernel, integrate with the .NET systems you already run, and hold up when real users start asking real questions.
Why enterprise LLM projects stall between pilot and production
-
LLM answers confidently, but not always correctly
Without RAG, a model guesses at questions about your products, contracts, or internal process, and it states the wrong answer in the same tone it uses for a right one. A general-purpose model has never seen your data, so it fills the gap with whatever sounds realistic.
-
Naive RAG fails on actual enterprise documents
A basic setup that chunks a document, embeds it, and retrieves the closest match works fine on a simple question. It breaks down on long PDFs, tables, and questions that need information pulled from more than one source. Most teams that tried RAG once and gave up on it ran into exactly this wall.
-
LLM lives outside your systems
A working prototype often sits on its own, disconnected from the CRM, the ERP, and the .NET backends where your data lives. The model can hold a conversation, but the answer never reaches the process that needed it.
-
API costs spiral out of control
Without cost monitoring, token caching, and prompt optimization, a single active LLM product in production can generate API bills in the thousands of dollars a month before anyone even notices.
Our LLM & RAG development services

LLM application development
Enterprise search, copilots, document intelligence, and workflow automation built on top of an LLM. Our LLM application development services turn a general-purpose model into one that answers from your business, not from a training set built for the all internet users in general.
Agentic RAG
Multi-hop retrieval and reasoning loops that let RAG work alongside AI agents on complex, multi-step questions, pulling from multiple sources and combining them into one answer instead of stopping at the first match.
RAG pipeline architecture and development
Our custom RAG development services combine hybrid search across vector and keyword indexes, reranking, contextual chunking, and metadata filtering, so retrieval holds up on documents more complicated than a short FAQ.
LLM integration into existing apps
Connecting an LLM to your .NET applications, your SaaS tools, and the legacy systems you already run. Our LLM app development services focus on wiring the model into where your team already works, instead of shipping another standalone tab.
LLM fine-tuning and domain adaptation
We adapt GPT-4o, Mistral, or an open-source LLM to your domain-specific terminology and tone, for the cases where retrieval alone isn’t enough and the model itself needs to speak your industry’s language.
RAG evaluation and optimization
Our RAG AI development services include RAGAS metrics, retrieval accuracy tracking, hallucination rate testing, and pipeline tuning, so you know how the system performs before your users find it too complicated.
Why enterprises choose Blackthorn Vision as their LLM development company
-
Azure OpenAI + Semantic Kernel
We are a Microsoft Partner with deep technical integration into Azure AI, built with the compliance, data residency, and security controls an enterprise deployment needs. As a custom LLM development company, that depth is what separates our work from a thin call to the GPT API.
-
.NET-native LLM & RAG integration
Fifteen-plus years of .NET work gives us a real edge here: LLMs and RAG pipelines that connect to your enterprise systems instead of standing next to them. The team that builds the model and the team that builds the integration are the same people.
-
Production RAG beyond naive chunking
Hybrid search, reranking, multi-index retrieval, and agentic RAG for multi-hop questions. Most RAG failures come down to retrieval failures, and we spend most of our engineering time closing that gap. It’s a large part of why clients call us for the best RAG development services on the Microsoft stack.
-
LLMOps from day one
Cost monitoring, token caching, prompt optimization, evaluation pipelines, and drift detection keep a system accurate and affordable long after launch. Blackthorn Vision is a Microsoft-partnered .NET and AI development company that helps enterprise teams build and modernize complex software products, and exactly because of that combination enterprise clients call us among the best LLM development company options for regulated, Microsoft-stack work, including teams searching for an LLM development company in USA.
Technologies we use for LLM & RAG development
All technologiesWe choose the model, the retrieval strategy, and the orchestration layer based on your data, latency needs, and compliance team requirements.
Fine-tuning has its own category here because we can adapt a model to your domain when retrieval alone falls short, instead of only calling an API. Evaluation and LLMOps get their own category too, since a pipeline nobody measures is a pipeline that keeps getting worse.
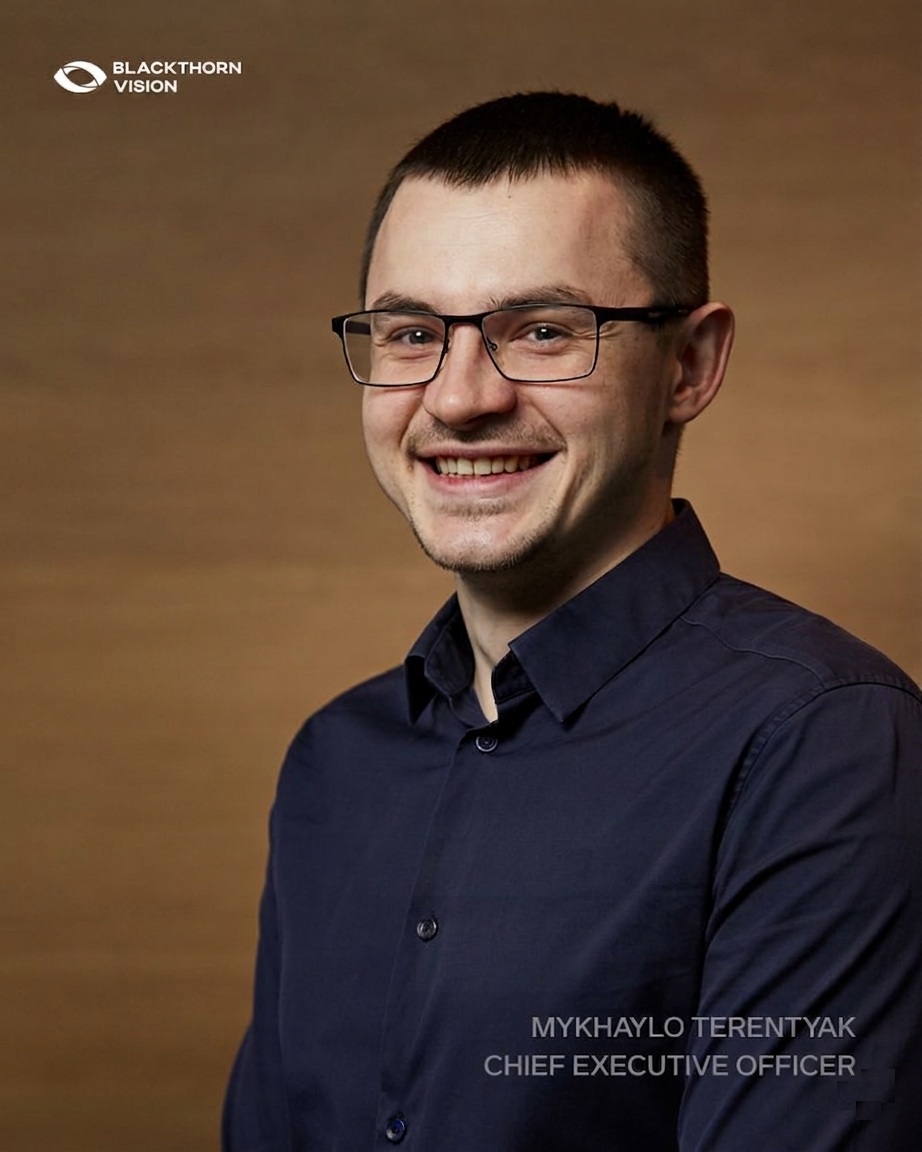
Meet the LLM & RAG development team at Blackthorn Vision
LLM without RAG hallucinates, we all know this. At the same time, RAG without LLMOps degrades over time. None of this situations is acceptable for a big enterprise and that’s why, we build the whole system.”
Mykhailo Terentiak, Founder & CEO
How Blackthorn Vision builds your LLM & RAG solution

-
01
Use case and data assessment
We look at the task, the data behind it, your accuracy and latency requirements, and any applicable compliance rules. The deliverable is an LLM/RAG feasibility report with a recommended architecture.
-
02
Architecture design
We choose the model, settle the RAG strategy, and design chunking, retrieval, and integration points to deliver a comprehensive solution architecture document.
-
03
Development and integration
We build the LLM/RAG pipeline, connect it to your .NET systems through custom connectors, handle the prompt engineering, and build a UI if the project needs one. The result is a working LLM/RAG solution as part of our custom RAG development services.
-
04
Evaluation and tuning
We run RAGAS metrics on the pipeline, track retrieval accuracy and hallucination rate, and check latency and cost against your targets. You receive an evaluation report and a tuned pipeline.
-
05
LLMOps and monitoring
We set up cost monitoring, token caching, a model update strategy, and drift detection before handing over the system. Deliverable: your live solution plus an LLMOps dashboard, and continued support as part of our LLM development services.
FAQ
-
What is the difference between LLM development and RAG development?
-
How do you manage and control LLM API costs in production?
Token caching so repeat questions don’t cost twice, prompt optimization to cut unnecessary tokens, and cost monitoring dashboards that flag a spending spike before it turns into a surprise invoice.
-
How do you integrate LLM/RAG solutions with our existing .NET or enterprise systems?
Through custom .NET connectors built by the same team that designs the LLM and RAG pipeline. Fifteen-plus years of .NET work means we connect to your CRM, ERP, and legacy backends without a rewrite of what’s already running.
-
How do you prevent hallucinations in production LLM applications?
Grounding every answer in retrieved source documents through RAG, hybrid search so retrieval doesn’t miss the right passage, reranking to surface the best match, and evaluation with RAGAS to catch a rising hallucination rate before your users do.
-
Which LLM models do you work with: GPT-4o, Claude, Gemini, or open-source?
We work with all of them. We default to Azure OpenAI’s GPT-4o for Microsoft-stack enterprise clients, and we bring in Anthropic Claude, Google Gemini, Mistral, or Llama 3 where the use case, cost target, or compliance requirement points that way.
-
Do I need RAG, fine-tuning, or both for my use case?
RAG is usually the right first move when the model needs current, specific facts from your documents, since it’s faster to set up and easier to update. Fine-tuning makes sense when you need the model to adopt a domain vocabulary or a particular tone, on top of what retrieval alone can give it. We’ll tell you which one your case needs after reviewing your data.